I am getting warnings when compiling some ST Cube code. These are the two functions
/**
  * @brief  USB_WritePacket : Writes a packet into the Tx FIFO associated
  *         with the EP/channel
  * @param  USBx  Selected device
  * @param  src   pointer to source buffer
  * @param  ch_ep_num  endpoint or host channel number
  * @param  len  Number of bytes to write
  * @param  dma USB dma enabled or disabled
  *          This parameter can be one of these values:
  *           0 : DMA feature not used
  *           1 : DMA feature used
  * @retval HAL status
  */
HAL_StatusTypeDef USB_WritePacket(USB_OTG_GlobalTypeDef *USBx, uint8_t *src, uint8_t ch_ep_num, uint16_t len, uint8_t dma)
{
  uint32_t USBx_BASE = (uint32_t)USBx;
  uint32_t *pSrc = (uint32_t *)src;
  uint32_t count32b, i;

  if (dma == 0U)
  {
    count32b = ((uint32_t)len + 3U) / 4U;
    for (i = 0U; i < count32b; i++)
    {
      USBx_DFIFO((uint32_t)ch_ep_num) = *((__packed uint32_t *)pSrc);
      pSrc++;
    }
  }

  return HAL_OK;
}

/**
  * @brief  USB_ReadPacket : read a packet from the Tx FIFO associated
  *         with the EP/channel
  * @param  USBx  Selected device
  * @param  dest  source pointer
  * @param  len  Number of bytes to read
  * @param  dma USB dma enabled or disabled
  *          This parameter can be one of these values:
  *           0 : DMA feature not used
  *           1 : DMA feature used
  * @retval pointer to destination buffer
  */

void *USB_ReadPacket(USB_OTG_GlobalTypeDef *USBx, uint8_t *dest, uint16_t len)
{
  uint32_t USBx_BASE = (uint32_t)USBx;
  uint32_t *pDest = (uint32_t *)dest;
  uint32_t i;
  uint32_t count32b = ((uint32_t)len + 3U) / 4U;

  for (i = 0U; i < count32b; i++)
  {
    *(__packed uint32_t *)pDest = USBx_DFIFO(0U);
    pDest++;
  }
  return ((void *)pDest);
}
The macro USBx_DFIFO is
#define USBx_DFIFO(i) *(__IO uint32_t *)(USBx_BASE + USB_OTG_FIFO_BASE + ((i) * USB_OTG_FIFO_SIZE))
The macro __IO is just "volatile" and is used for CPU registers.
The code works. It is a loop which copies across 64 bytes, in 16 moves, each one 4 bytes. One could use DMA for it (this came up in a thread here long ago) but by the time DMA was set up, you don't gain anything.
I am getting these warnings:
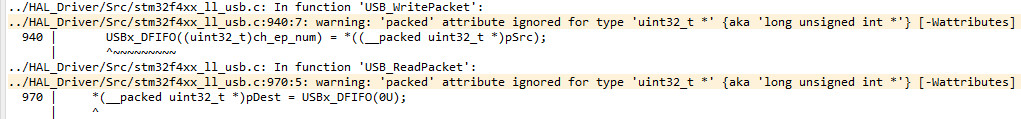
Someone had a look at this and thought the "packed" is completely meaningless, and there is a lot of ST Cube code which that applies to, and indeed removing it doesn't break anything, but I wonder if anyone here can think of a reason the programmer did that. One normally uses 'packed' on structs.
It is not meaningless, it indicates that alignment may be arbitrary, not 4 bytes in this case. You can see that pSrc was obtained by casting uint8_t* buffer to uint32_t*, so the buffer is generally not aligned.
But I'm not sure GCC ever supported it that way, I think this is ARM/Keil feature. I'm not even sure they implemented it when moving to Keil5, which is based on Clang. But I guess they might have for compatibility.
I don't think 'packed' makes any sense for a pointer. It's an attribute meant for a struct definition. 'Packed' guarantees that struct members are not padded. It is absolutely meaningless for qualifying a pointer.
It makes sense for the pointed data though. __packed here says that uint32_t pointed by the pointer is not aligned (pointer lower bits are not 00). Without this the code here is not correct. This cast " uint32_t *pSrc = (uint32_t *)src;" is wrong given that src is uint8_t*.
So compiler would be forced to generate 4 bytes load/stores instead of one word load/store for architectures that don't support unaligned access.
It makes sense for the pointed data though. __packed here says that uint32_t pointed by the pointer is not aligned (pointer lower bits are not 00). Without this the code here is not correct. This cast " uint32_t *pSrc = (uint32_t *)src;" is wrong given that src is uint8_t*.
So compiler would be forced to generate 4 bytes load/stores instead of one word load/store for architectures that don't support unaligned access.
I see, but I don't think GCC supports that, at least with this attribute. I'll have to check.
GNUC supports things like
struct __dealign_uint16 { uint16_t datum; } __attribute__((packed));
struct __dealign_uint32 { uint32_t datum; } __attribute__((packed));
struct __dealign_uint64 { uint64_t datum; } __attribute__((packed));
to misalign data, but I don't think there is a type generic way for non-struct data types.
I just played a bit with godbolt. GCC and Clang support packing of individual struct members:
struct foo
{
    char one;
    __packed short two;
    char three;
    int four;
} c;
But not packing for the individual variables.
I just played a bit with godbolt. GCC and Clang support packing of individual struct members:
struct foo
{
    char one;
    __packed short two;
    char three;
    int four;
} c;
But not packing for the individual variables.
That's a useful thing to remember. I've only packed whole structures for things like the dealign macros I showed earlier, and making a structure match the layout of packets.
Can anyone suggest the right way to do this which runs fastest?
I can probably make sure the RAM buffer is 4 byte aligned. Currently, AFAICT by working through a dozen nested calls in the horrid USB code, the buffer is
static uint8_t cdc_receive_temp_buffer[64];
static uint8_t cdc_out_buf[256];
Neither is aligned, but presumably putting __attribute__ ((aligned (4))) after each would do it.
In reality both buffers are aligned but that could be just fortunate since both are in the FreeRTOS stack area and there are no objects smaller than 4 bytes before them
static void USBThread(void *argument)
{

	#define CDCTXBUFSIZE 256

	MX_USB_DEVICE_Init();

	g_USB_started=true;				// Enables port 0 (KDE -> PC) output functions

	uint32_t ms_before_eject = 0;
	static uint8_t cdc_out_buf[CDCTXBUFSIZE];	// linear buffer for USB data
The 32F4 doesn't need alignment for uint32_t but it would run slower.
The most portable way is to combine the byte buffer into a single variable by shifting each byte into the multi-byte variable. Anything is just praying that it works. It is the main reason why I avoid casting multi-byte variables / structs onto byte buffers.
Besides,
#include <stdint.h>

uint32_t get_u32le(const unsigned char *const src) {
    return ((uint32_t)(src[0])) | ((uint32_t)(src[1]) << 8) | ((uint32_t)(src[2]) << 16) | ((uint32_t)(src[3]) << 24);
}

uint32_t get_u32be(const unsigned char *const src) {
    return ((uint32_t)(src[0]) << 24) | ((uint32_t)(src[1]) << 16) | ((uint32_t)(src[2]) << 8) | ((uint32_t)(src[3]));
}

uint32_t get_u32(const unsigned char *const src) {
#if __BYTE_ORDER__ == __LITTLE_ENDIAN__
    return ((uint32_t)(src[0])) | ((uint32_t)(src[1]) << 8) | ((uint32_t)(src[2]) << 16) | ((uint32_t)(src[3]) << 24);
#else
    return ((uint32_t)(src[0]) << 24) | ((uint32_t)(src[1]) << 16) | ((uint32_t)(src[2]) << 8) | ((uint32_t)(src[3]));
#endif
}
compiles to quite acceptable code with both GCC and clang on all architectures when using -Og, -Os, or -O2.
The only one I wasn't sure about is risc-v (rv32gc), but even on that one,
#include <stdint.h>

struct word32 {
    uint32_t u32 __attribute__((packed));
} __attribute__((packed));

uint32_t get_u32(const unsigned char *const src) {
    return ((const struct word32 *)src)->u32;
}
compiles to the same code; I assume rv32gc doesn't like unaligned 32-bit accesses. On x86-64, where unaligned accesses are okay (just slower), these compile to a simple load (plus a bswap for get_u32be).
The most portable way is to combine the byte buffer into a single variable by shifting each byte into the multi-byte variable.
I do that too, to ensure byte order when storing e.g. a uint32 in an EEPROM.
But this is different. It needs to be very fast. The CPU register is 32 bits wide and it should be done in
16 moves.
The CPU register is 32 bits wide and [copying a 64-byte buffer to it] should be done in 16 moves.
Just because you do 16 stores, does not mean you have to do exactly 16 loads, too.
HAL_StatusTypeDef USB_WritePacket(USB_OTG_GlobalTypeDef *USBx, uint8_t *src, uint8_t ch_ep_num, uint16_t len, uint8_t dma)
{
  uint32_t USBx_BASE = (uint32_t)USBx;
  uint32_t *pSrc = (uint32_t *)src;
  uint32_t count32b, i;

  if (dma == 0U)
  {
    count32b = ((uint32_t)len + 3U) / 4U;
    for (i = 0U; i < count32b; i++)
    {
      USBx_DFIFO((uint32_t)ch_ep_num) = get_u32(pSrc + i);
    }
  }

  return HAL_OK;
}

void *USB_ReadPacket(USB_OTG_GlobalTypeDef *USBx, uint8_t *dest, uint16_t len)
{
  uint32_t USBx_BASE = (uint32_t)USBx;
  uint32_t *pDest = (uint32_t *)dest;
  uint32_t i;
  uint32_t count32b = ((uint32_t)len + 3U) / 4U;

  for (i = 0U; i < count32b; i++)
  {
    set_u32(pDest + i, USBx_DFIFO(0U);
  }
  return ((void *)pDest);
}
which on stm32f4, because it supports unaligned 32-bit accesses, will optimize the get_u32() and set_u32() calls to ordinary loads and stores. You can implement them for example as
struct unaligned_u32 {
    uint32_t  u32 __attribute__((packed));
} __attribute__ ((packed));

static inline uint32_t  get_u32(const void *const src)
{
    return ((const struct unaligned_u32 *)src)->u32;
}

static inline uint32_t  set_u32(void *const dst, uint32_t val)
{
    ((struct unaligned_u32 *)dst)->u32 = val;
    return val;
}
In any case, a better solution is to use
HAL_StatusTypeDef USB_WritePacket(USB_OTG_GlobalTypeDef *USBx, const uint32_t *src, uint_fast8_t ch_ep_num, uint_fast8_t words, uint_fast8_t dma)
{
  const uintptr_t USBx_BASE = (uintptr_t)USBx;

  if (dma == 0U) {
    const uint32_t *p = src;
    const uint32_t *const q = src + words;

    while (p < q) {
      USBx_DFIFO((uint32_t)ch_ep_num) = *(p++);
    }
  }

  return HAL_OK;
}

uint32_t *USB_ReadPacket(USB_OTG_GlobalTypeDef *USBx, uint32_t *dst, uint_fast8_t words)
{
  const uintptr_t USBx_BASE = (uintptr_t)USBx;

  uint32_t *p = dst;
  uint32_t *const q = dst + words;

  while (p < q) {
    *(p++) = USBx_DFIFO(0U);
  }

  return dst;
}
and declaring
uint32_t cdc_out_buf[(CDCTXBUFSIZE + 3)/4];.
If you need to access the buffer data at some byte offset, you can always use
(offset + (unsigned char *)cdc_out_buf) as the unsigned char pointer to that byte.
Unfortunately you have stretched my C expertise past its limit there

What is actually wrong with the existing (ST) code assuming the buffers are explicitly 4-aligned?
Just because you do 16 stores, does not mean you have to do exactly 16 loads, too.
I think it
does.
AIUI, if a RAM buffer, accessed as uint32, is not 4-aligned, and given that in many/most cases the 32F4
requires a 32 bit reg to be written (and sometimes read, too, AFAIK, especially status registers where a read clears a bit so you need to read all 32 in one go) via a
32 bit variable, a 16 word move from RAM to a 32 bit reg will perform
64 RAM reads and 16 register writes, or the opposite (16 reg reads and 64 RAM writes). Nobody is likely to notice because the RAM access is zero wait state (7ns cycle time) but it will be slower by 336ns (48x7).
FWIW the code shows the stupidity of ST code because dma=0 always (on USB FS; only USB HS uses DMA)
I see I removed that test from one of the two functions...
I can probably make sure the RAM buffer is 4 byte aligned.
This is the easiest and cleanest way of dealing with this.
Neither is aligned, but presumably putting __attribute__ ((aligned (4))) after each would do it.
You don't even need non-standard attributes. C11 includes stdalign.h, so all you need to do is this:
#include <stdalign.h>
static alignas(4) uint8_t cdc_receive_temp_buffer[64];
static alignas(4) uint8_t cdc_out_buf[256];
Thanks. Yes, I found those macros too.
Mods done, and it still runs
I posted the question on th ST forum (where usually there are no replies) and got one
https://community.st.com/s/question/0D73W000001i4NaSAI/detail?fromEmail=1&s1oid=00Db0000000YtG6&s1nid=0DB0X000000DYbd&s1uid=0053W000001ojJ3&s1ext=0&emkind=chatterCommentNotification&emtm=1666118332031&t=1666121247984This is for read/write a multibyte value (32-bit in this case) from/to unaligned location.
For gcc, __packed should be defined somewhere as __attribute__((packed)).
Alternatively, for any compiler use the CMSIS (ARM-defined) macros __UNALIGNED_UINT32_READ, __UNALIGNED_UINT32_WRITE -I don't understand it.
Has to be said though that just because the 64 byte buffer
is aligned, nobody actually knows whether all USB transfers are aligned
within that buffer.
I think, for receiving, the USB ISR (the USB code is totally ISR based) always starts at the start of that 64 byte buffer but it may transfer a number of bytes which is not a multiple of 4, and that means the last buffer write will be done one byte at a time (1-3 bytes).
And for transmission, where I am supplying a 256 byte buffer, I again think it starts from the beginning of it but have no idea what it does with it. And since USB
CDC never transfers more than 64 bytes, if I give it say 211 bytes in that buffer, it must be doing 64,64,64 and then 19.
USB
MSC is always 512 bytes (transferred as 8 x 64), and those functions are different:
/**
  * @brief  .
  * @param  lun: .
  * @retval USBD_OK if all operations are OK else USBD_FAIL
  */
int8_t STORAGE_Read_FS(uint8_t lun, uint8_t *buf, uint32_t blk_addr, uint16_t blk_len)
{
	Adesto_FLASH_ReadPage(buf, blk_len * STORAGE_BLK_SIZ, blk_addr * STORAGE_BLK_SIZ);
	return (USBD_OK);
}
and the transfer from FLASH to a 512 byte buffer which USB MSC then reads is done with DMA, in Adesto_FLASH_ReadPage(). I ought to check those buffers are aligned too.
I don't understand it.
They are saying that you need to use those alignment attributes. But I don't see it working with GCC when used like this. No idea where this code was tried. May be there is some version of GCC that supports this use.
I think, for receiving, the USB ISR (the USB code is totally ISR based) always starts at the start of that 64 byte buffer but it may transfer a number of bytes which is not a multiple of 4, and that means the last buffer write will be done one byte at a time (1-3 bytes).
The code you provided assumes that the buffer size is multiple of 4 bytes and only transfers words. USB FIFO is word-only transfer and the code makes no attempts to split the word into bytes. No idea if this is an oversight or an API requirement.
And for transmission, where I am supplying a 256 byte buffer, I again think it starts from the beginning of it but have no idea what it does with it. And since USB CDC never transfers more than 64 bytes, if I give it say 211 bytes in that buffer, it must be doing 64,64,64 and then 19.
You still write multiple of 4 bytes, but then the length register specifies how many bytes to actually transfer. If your buffer is not a multiple of 4 you will just write some junk at the end, but it will never be transmitted, so it does not matter.
I just played a bit with godbolt. GCC and Clang support packing of individual struct members:
struct foo
{
    char one;
    __packed short two;
    char three;
    int four;
} c;
But not packing for the individual variables.
It supports this, for instance.
Yes, that would do the trick. As ataradov mentioned above, using alignas(1) instead of a GCC attribute would do the same and be standard C11, although alignas() doesn't seem to be accepted in the context of a type definition, unfortunately.
With all that said, there's something I don't quite get. If you want the compiler to enforce the alignment you set for a given structure whena accessing fields, just dereference a pointer to the structure instead of messing with pointers to members (and risk getting alignment completely wrong.)
struct->field will access the field with whatever alignment was defined for the structure being pointed to.
They are saying that you need to use those alignment attributes. But I don't see it working with GCC when used like this. No idea where this code was tried. May be there is some version of GCC that supports this use.
Sure, I get that, but he doesn't say why, and more to the point doesn't say why it works without them. I have just intentionally misaligned the CDC buffer by 1 byte and it still all runs.
May be there is some version of GCC that supports this use.
I am now on GCC v10 and the ST code I am using was brought into the project ~ 3 years ago when GCC was on v7 (Cube was 1.4). This is from my notes when testing it:
Cube 1.5.1 has a compiler version 7.3.1 20180622.
Cube 1.6.1 has a compiler version 9.3.1 20200408.
Cube 1.7.0 is the same as 1.6.1.
Cube 1.8.0 is the same again (no change in compiler or linker)
Cube 1.9.0 has a compiler v10 which does stricter checking of various things
Cube 1.10 is same as 1.9 but crashes more oftenSo maybe v7 supported it. But the fact is that it
works with those __packed attribs
ignored. And the code does get tested exhaustively all day; both CDC and MSC. That said, an overhead of
3xx ns per 64 bytes will go totally unnoticed. This is a tiny fraction of nothing
I have the CDC buffers aligned but can't find the 512 byte MSC buffers, due to the way the MSC functions are called via multiple levels of indirection, via function tables etc. FWIW, a breakpoint on the r/w functions shows the buffers
are aligned.
And the code does get tested exhaustively all day;
It is not about how hard you test and given binary. Your buffers may shift after you make a change to the code. But when it happens the failure would be obvious and instant.
I did misalign them, as I wrote above. Still works. And arguably it should work, given that the 32F4 supports unaligned 32 bit loads and stores.
IIRC, some members of the 32F family do not support unaligned data.
And arguably it should work, given that the 32F4 supports unaligned 32 bit loads and stores.
Well yes, if unaligned traps are not enabled, it would work. The only thing to keep in mind is that ldrd/strd do not support unaligned access, but that's generally not a problem.
All Cortex-M3/M4/M7 devices should support unaligned access. I don't think there is even an option in IP to disable that.